Growth / Performance
Kalle Mobeck
•

Geo Lift Testing: How Power Analysis and L2 Imbalance Save Budget
A geo lift test measures the incremental sales, revenue, or conversions caused by running a campaign in some regions while holding others back as a control. It compares the treated markets against a synthetic version of what those markets would have done without the campaign. The output is a lift percentage and a dollar figure, and it’s built for channels like TV, CTV, and out-of-home where you can’t run a clean user-level holdout.
TL;DR:
Accurate pre-test validation with sufficient historical data (ideally six months or more) is essential to ensure a credible synthetic control fit.
Proper market matching, using clustering or geographic tools like GMAs, prevents contamination and improves the accuracy of treatment and control comparisons.
Power analysis helps determine the minimum sample size and test duration needed to reliably detect expected lift effects, avoiding inconclusive results.
A significant lift combined with a good pre-period fit supports scaling, while high imbalance calls for re-matching markets before acting.
Running geo lift tests requires disciplined planning, including locking controls, monitoring compliance, and interpreting results alongside power and fit metrics.
Table of Contents
What Is Geo Lift Testing and When Should You Use It?
Why Geo Lift Testing Matters for Budget Decisions
How Does Synthetic Control Build the Counterfactual?
How Much Sample Size Do You Need for a Geo Test?
How Do You Select Markets and Prevent Contamination?
What Does a Geo Lift Test Timeline Look Like?
How Do You Read and Act on Geo Lift Results?
What Are the Most Common Geo Lift Testing Mistakes?
An Agency Practitioner’s View on Running Geo Lift Programs
Where to Learn More About Geo Lift Testing Methodology
Sources
What Is Geo Lift Testing and When Should You Use It?
Geo lift testing splits geography into treatment and control groups instead of splitting users. You run media in one set of markets, hold spend back in a matched set of others, then compare what actually happened against a modeled counterfactual of what would have happened without the campaign. The gap between the two is your incremental lift.
This matters most where individual-level tracking breaks down. Platform holdouts work fine for search and paid social, where a user-level control group is easy to build. But TV, CTV, OOH, and most retail media placements don’t offer that granularity. Geo experiments fill the gap:
TV/CTV campaigns where impressions can’t be tied to individual devices reliably
Retail media and OOH where exposure is inherently regional
Cross-channel campaigns where you want one incrementality read across a full media mix, not channel-by-channel guesses
Marketing mix modeling (MMM) covers long-run, multi-channel attribution but runs on historical data and correlation. A geo lift test is a live experiment that produces causal evidence, and the two methods work best paired together.
Why Geo Lift Testing Matters for Budget Decisions
The core value is causal proof, not correlation. A geo lift test tells you what a campaign actually caused, which is a different and stronger claim than “sales went up while the campaign ran.” That distinction is what gets a channel funded or defunded at the next budget review.
It’s also privacy-safe by design. Because the unit of measurement is a market, not a device or a cookie, geo lift testing works cleanly across the walled gardens and channels where individual tracking is disappearing.
The outputs stakeholders actually use:
Lift %: the incremental change in the KPI versus the modeled counterfactual
Incremental revenue or conversions: lift converted into a dollar or unit figure
Incremental ROAS (iROAS): incremental revenue divided by incremental spend
A recommendation: scale, hold, or cut the channel based on the result
Pro Tip: Report iROAS alongside blended ROAS in every readout. Stakeholders who only see blended numbers tend to overcredit channels that were already going to convert anyway.
How Does Synthetic Control Build the Counterfactual?
The counterfactual is the hardest part of a geo test, and it’s also where most of the credibility lives. Synthetic control methods solve this by building a weighted combination of untreated “donor” markets that closely tracks the treated market’s pre-campaign trend. Instead of picking one lookalike city, the model blends several, weighted to minimize the gap between the synthetic market and the real one before treatment starts.
GeoLift, the open-source R package built on this approach, extends it with Augmented Synthetic Control Methods (ASCM) and Generalized Synthetic Control (GSC), which handle interactive fixed effects and heterogeneous treatment effects better than a basic weighted average. GeoLift’s methodology runs inference through parametric bootstrapping to generate p-values, rather than relying on standard errors that assume a normal distribution.
Before trusting any output, check the fit:
Pre-period RMSE: how closely the synthetic market tracked the real one before treatment
L2 imbalance: a raw measure of pre-period mismatch
Scaled L2 Imbalance: a bounded version of that same metric, useful for comparing fit across different KPIs and test sizes
A synthetic control that fits poorly before treatment starts will produce a lift number nobody should trust. Scaled L2 Imbalance exists precisely so analysts can judge that fit on a consistent scale, no matter what KPI or market size the test uses.
How Much Sample Size Do You Need for a Geo Test?
Power analysis is the step most teams skip, and it’s the single biggest reason geo tests come back inconclusive. Skipping it doesn’t make the test faster. It just means “no significant lift” could mean the campaign didn’t work, or it could mean the test was never capable of detecting it in the first place.
The mechanics work like this:
Define your expected lift, usually from a past campaign, a category benchmark, or a conservative planning estimate.
Translate that into a minimum detectable effect (MDE), the smallest lift your test setup can reliably distinguish from noise.
Feed baseline variance and conversion volume into a power calculator. Noisier or lower-volume KPIs need more markets or more time to hit the same MDE.
Run GeoLift’s power simulation across candidate market counts and test lengths before locking anything in.
Check the budget math. A test that requires 20 markets and eight weeks to detect a 3% lift may cost more in held-back media than the insight is worth.
As a rule of thumb, smaller expected effects need proportionally larger donor pools and longer windows to clear statistical significance. GeoLift’s documentation is direct about this: a null result without a prior power check is not evidence of no effect. It’s evidence the test was underpowered.
How Do You Select Markets and Prevent Contamination?
Market selection is where most geo tests quietly fail before they even launch. Treatment and control markets need to match on historical trend, demographic composition, and prior exposure to the channel being tested. A control market that looks similar on population size but tracks a different sales trend will wreck your pre-period fit.
Modern tools automate this instead of relying on gut-feel picks:
Clustering algorithms group similar markets before assignment
Synthetic selection routines in GeoLift test combinations of candidate markets against power requirements automatically
Google Marketing Areas (GMAs), used in Google’s Conversion Lift geo-split methodology, are built specifically around commuting zones to limit cross-market bleed
Contamination, often called bleed, happens when people in a control market see the treatment campaign anyway, usually through commuting patterns or loosely targeted media. Tighten geo-targeting settings, pause overlapping national campaigns during the test window, and favor GMAs or commuting-zone clusters over arbitrary city boundaries.
Pro Tip: If two candidate markets share a media market or a major highway commuter corridor, treat them as one unit, not two independent geographies.
What Does a Geo Lift Test Timeline Look Like?
A geo lift test has three phases, and skipping any one of them tends to show up as a bad readout later. The recommended sequence:
Pre-test validation (4 to 8 weeks minimum, ideally 6+ months of historical KPI data). Confirm treatment and control markets track each other closely before you spend a dollar.
Lock operational controls before launch. No concurrent promotions in treatment markets, strict geo-targeting with no national overlap, and a single owner accountable for monitoring compliance.
Run the treatment window. Length depends on channel and funnel: shorter for direct-response search-adjacent channels, longer, often 4 to 8 weeks, for upper-funnel or longer sales cycles.
Add a washout period after treatment ends. This captures delayed conversions and prevents the post-test window from bleeding into your next campaign cycle.
Assign roles explicitly: one owner for data pulls, one for targeting compliance, one for the final read.
Data hygiene matters as much as the model. Pull consistent regional KPI definitions across every market before the test starts, not after you’re already troubleshooting a bad fit.
How Do You Read and Act on Geo Lift Results?
A results readout needs four numbers before anyone makes a decision: lift %, p-value, the confidence interval around that lift, and Scaled L2 Imbalance for the pre-period fit. If the imbalance metric is high, the lift number underneath it needs a caveat regardless of how clean the p-value looks.
From there:
Convert lift into incremental revenue using your actual price or margin data, not a rough average
Divide incremental revenue by incremental spend to get iROAS, then compare it against your MMM’s channel estimate for the same period
A non-significant result isn’t a verdict. Check power first. If the test was underpowered, extend the window or expand markets before drawing conclusions
Result pattern | What it likely means | Recommended action |
|---|---|---|
Significant lift, low L2 imbalance | Clean causal signal | Scale spend, feed result into MMM as a calibration point |
Significant lift, high L2 imbalance | Signal exists but counterfactual is shaky | Rerun with better-matched markets before scaling |
Non-significant, adequate power | Likely true null effect | Consider reallocating budget away from the channel |
Non-significant, low power | Inconclusive, not a null result | Extend test length or market count, then rerun |
What Are the Most Common Geo Lift Testing Mistakes?
Most failed geo tests trace back to a handful of repeat offenders:
Skipping power analysis. Running a test sized on intuition instead of a calculator almost guarantees an inconclusive result on anything but a huge effect.
Poorly matched markets. High pre-period RMSE or L2 imbalance means your counterfactual was broken from day one, and no amount of statistical dressing fixes that after the fact.
External confounders. A competitor promotion, a regional weather event, or a local news story hitting one market and not another can swamp a real effect.
Operational bleed. National campaigns running alongside the test, or loose geo-targeting, contaminate control markets and shrink your measured lift toward zero.
The fix for all four is the same discipline: validate pre-period fit before launch, lock down targeting during the test, and treat power analysis as a gate, not a nice-to-have. Traditional matched market testing suffered from exactly these problems for years before synthetic control and automated market selection made the process far more reliable.
An Agency Practitioner’s View on Running Geo Lift Programs
Running a geo lift test well takes more than downloading GeoLift and picking cities off a map. It takes someone who can scope the power analysis correctly, negotiate media holdbacks with channel partners, and translate a Scaled L2 Imbalance figure into something a CMO will actually act on.
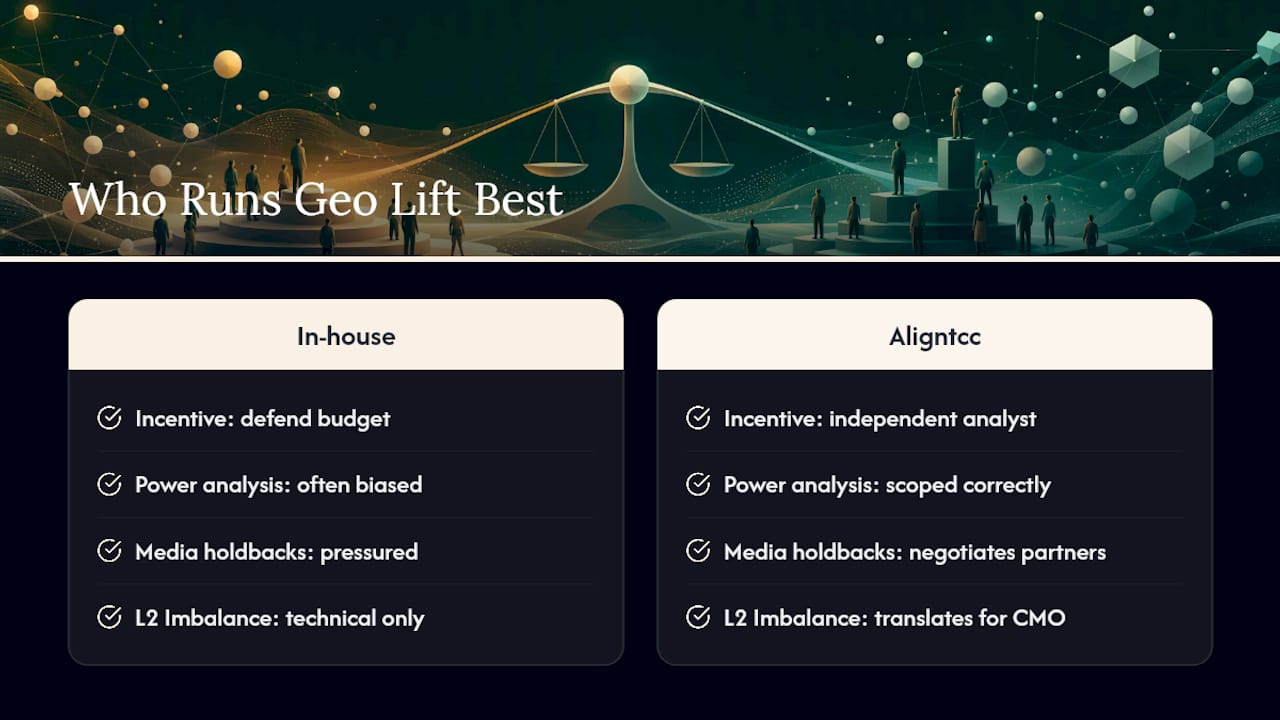
That’s the gap Aligntcc sits in for clients expanding across markets or launching in a new channel mix. Geo lift work sits alongside the go-to-market and paid media execution Aligntcc already runs for clients moving between Western and Chinese markets, where clean, causal read on regional campaign performance is often the only way to justify continued spend to a global board.
The agency model works because it separates the analytical rigor from the pressure to declare a win early. A test designed by the same team incentivized to defend the budget rarely gets an honest power analysis. An outside analytical partner has no reason to fudge the MDE.
— Kalle
Where to Learn More About Geo Lift Testing Methodology
For hands-on implementation, start with GeoLift’s methodology documentation and its GitHub walkthrough, which shows real power calculations and lift outputs on simulated data. Google’s Conversion Lift geo-split documentation covers the GMA-based alternative for search and video campaigns.
If you’re weighing test economics before committing budget, the sample-size thinking in experimental pricing design applies directly to geo test planning too: bigger effects need smaller samples, and small effects get expensive to detect fast.
Ready to build a geo lift program that survives scrutiny at the budget table? Talk to Aligntcc about scoping a test, from power analysis through market selection to the final readout.
Sources
Geo Lift Testing: How Power Analysis and L2 Imbalance Save Budget
THE POINT
Geo Lift Testing: How Power Analysis and L2 Imbalance Save Budget
KEY TAKEAWAYS
01
Geo lift testing driven by methodology: run power analysis, confirm synthetic control fit with Scaled L2 Imbalance, and protect media budgets.
02
Geo lift testing driven by methodology: run power analysis, confirm synthetic control fit with Scaled L2 Imbalance, and protect media budgets.
03
Geo lift testing driven by methodology: run power analysis, confirm synthetic control fit with Scaled L2 Imbalance, and protect media budgets.
RELATED INSIGHTS

LET’S TALK
What are you trying to grow next?
Brand, launch, market entry or performance. Book 30 minutes and tell us what you’re working on.